引言
网上找的好多收费的,离线的也不是很好用。
注意
此脚本针对于typecho的restful风格进行调优,其他站点请自行修改和完善。
正文
import requests
import re
from requests.packages import urllib3
import threading
import time

urllib3.disable_warnings()
urls = set()
baseUrl = "https://www.zunmx.top"
global threadNum
threadNum = 0
threadTotal = 20  # 最大线程数

header = {
    'Accept': 'text/html,application/xhtml+xml,application/xml;q=0.9,image/avif,image/webp,image/apng,*/*;q=0.8,application/signed-exchange;v=b3;q=0.9',
    'Accept-Encoding': 'gzip, deflate, br',
    'Accept-Language': 'zh-CN,zh;q=0.9',
    'Cache-Control': 'max-age=0',
    'Connection': 'close',
    'DNT': '1',
    'Host': baseUrl.replace("http://", "").replace("https://", ""),
    'sec-ch-ua': '" Not;A Brand";v="99", "Google Chrome";v="91", "Chromium";v="91"',
    'sec-ch-ua-mobile': '?0',
    'Sec-Fetch-Dest': 'document',
    'Sec-Fetch-Mode': 'navigate',
    'Sec-Fetch-Site': 'none',
    'Sec-Fetch-User': '?1',
    'Upgrade-Insecure-Requests': '1',
    'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36---ZUNMX-SITEMAP-CREATOR',
}


def getTitle(text):
    try:
        title = re.findall(r"(?<=title>).+?(?=</title)", text)
        if len(title) != 0:
            title = title[0]
        else:
            try:
                tmp = text.split('<title>')
                tmp2 = tmp[1].split("</title>")
                tmp3 = tmp2[0].replace(' ', '')
                title = tmp3
            except:
                # traceback.print_exc()
                title = "[ # ][Not Found Title]"
            finally:
                if title == '':
                    title = "[ # ][Not Found Title]"

        if title == "[ # ][Not Found Title]":
            try:
                tmp = text.split('<TITLE>')
                tmp2 = tmp[1].split("</TITLE>")
                tmp3 = tmp2[0].replace(' ', '')
                title = tmp3
            except Exception as e:
                title = "[ # ][Not Found Title]"
            finally:
                if title == '':
                    title = "[ # ][Not Found Title]"
    except:
        title = "[ # ][Not Found Title]"
    return title


def check_url(curr, data):
    url = re.findall(r"(?<=href=\").+?(?=\")|(?<=href=\').+?(?=\')", data)
    for i in url:
        if str(i).find("#") != -1:
            continue
        if str(i).find("index.php/feed/") != -1:
            continue
        if str(i).find(".css?") != -1:
            continue
        if str(i).find(".js?") != -1:
            continue
        if str(i)[len(i) - 4:len(i)] == ".css":
            continue
        if str(i)[len(i) - 3:len(i)] == ".js":
            continue
        if str(i).find(baseUrl) != 0:
            continue
        now = ""
        if str(i)[:1] == "/" and len(i) < 5:
            now = curr + i
        else:
            now = i
        if now not in urls:
            urls.add(now)
            requestURL(now)


def requestURL(url):
    global threadNum
    if url.find(baseUrl) != 0:
        return
    while threadNum > threadTotal - 1:
        time.sleep(1)
    threadNum += 1
    get = requests.get(url, verify=False, headers=header)
    threadNum -= 1

    if get.status_code == 200:
        print(url, getTitle(get.text), len(urls))
        threading.Thread(target=check_url, args=[url, get.text, ]).start()
    else:
        print("无效" + url, get.status_code, len(urls))


if __name__ == "__main__":
    requestURL(baseUrl)
    while threadNum > 0:
        time.sleep(2)  # 等待线程结束

    print(urls)

    gen = """<?xml version="1.0" encoding="UTF-8"?>
<!-- Sitemap for {0}generated at {1}-->
<!-- {2} links discovered creator zunmx -->
<urlset xmlns="http://www.google.com/schemas/sitemap/0.84"
xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
xsi:schemaLocation="http://www.google.com/schemas/sitemap/0.84
http://www.google.com/schemas/sitemap/0.84/sitemap.xsd">      """.format(baseUrl, str(time.time()), len(urls))
    for i in urls:
        gen += """
  <url>
    <loc>{0}</loc>
    <lastmod>{1}</lastmod>
    <changefreq>monthly</changefreq>
    <priority>0.9</priority>
  </url>
""".format(i, time.strftime("%Y-%m-%d", time.localtime()))
    gen += "</urlset>"

    with open("z:/sitemap.xml", "w") as f:
        f.write(gen)
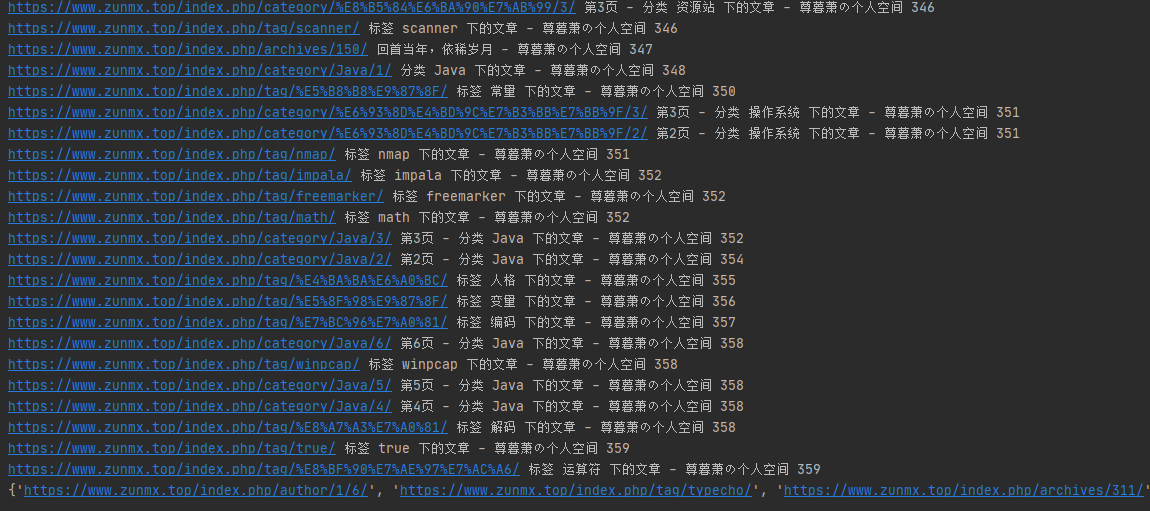
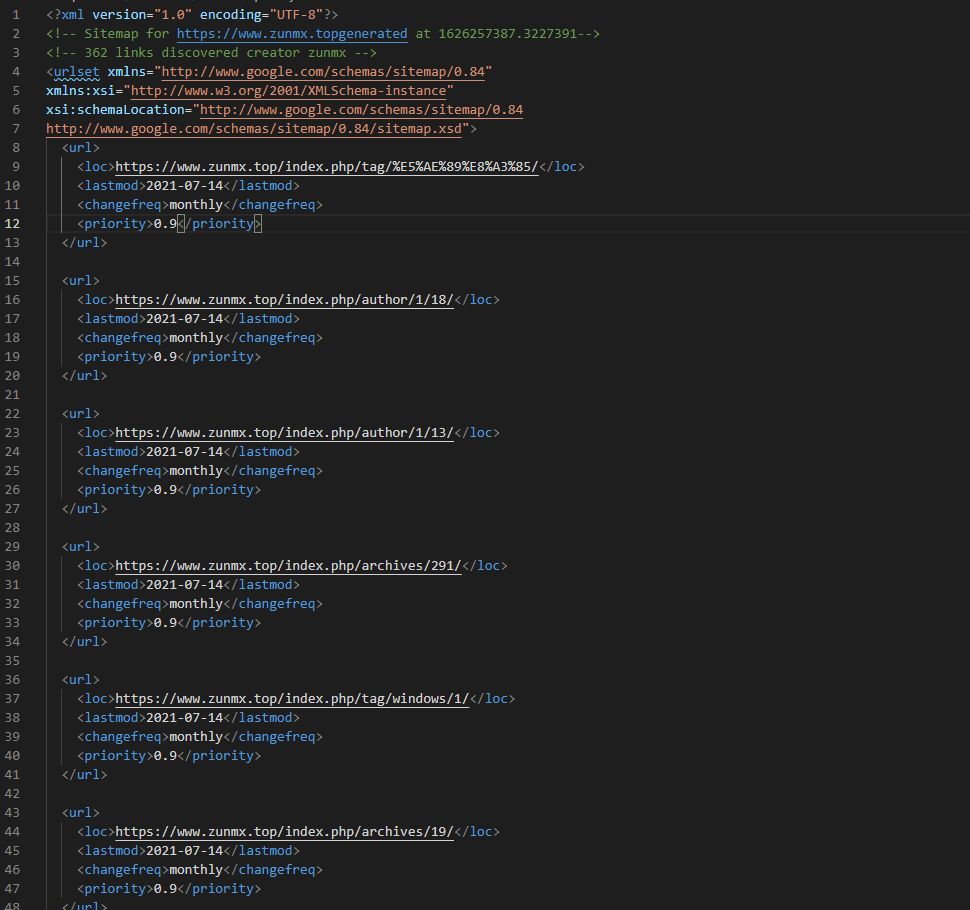
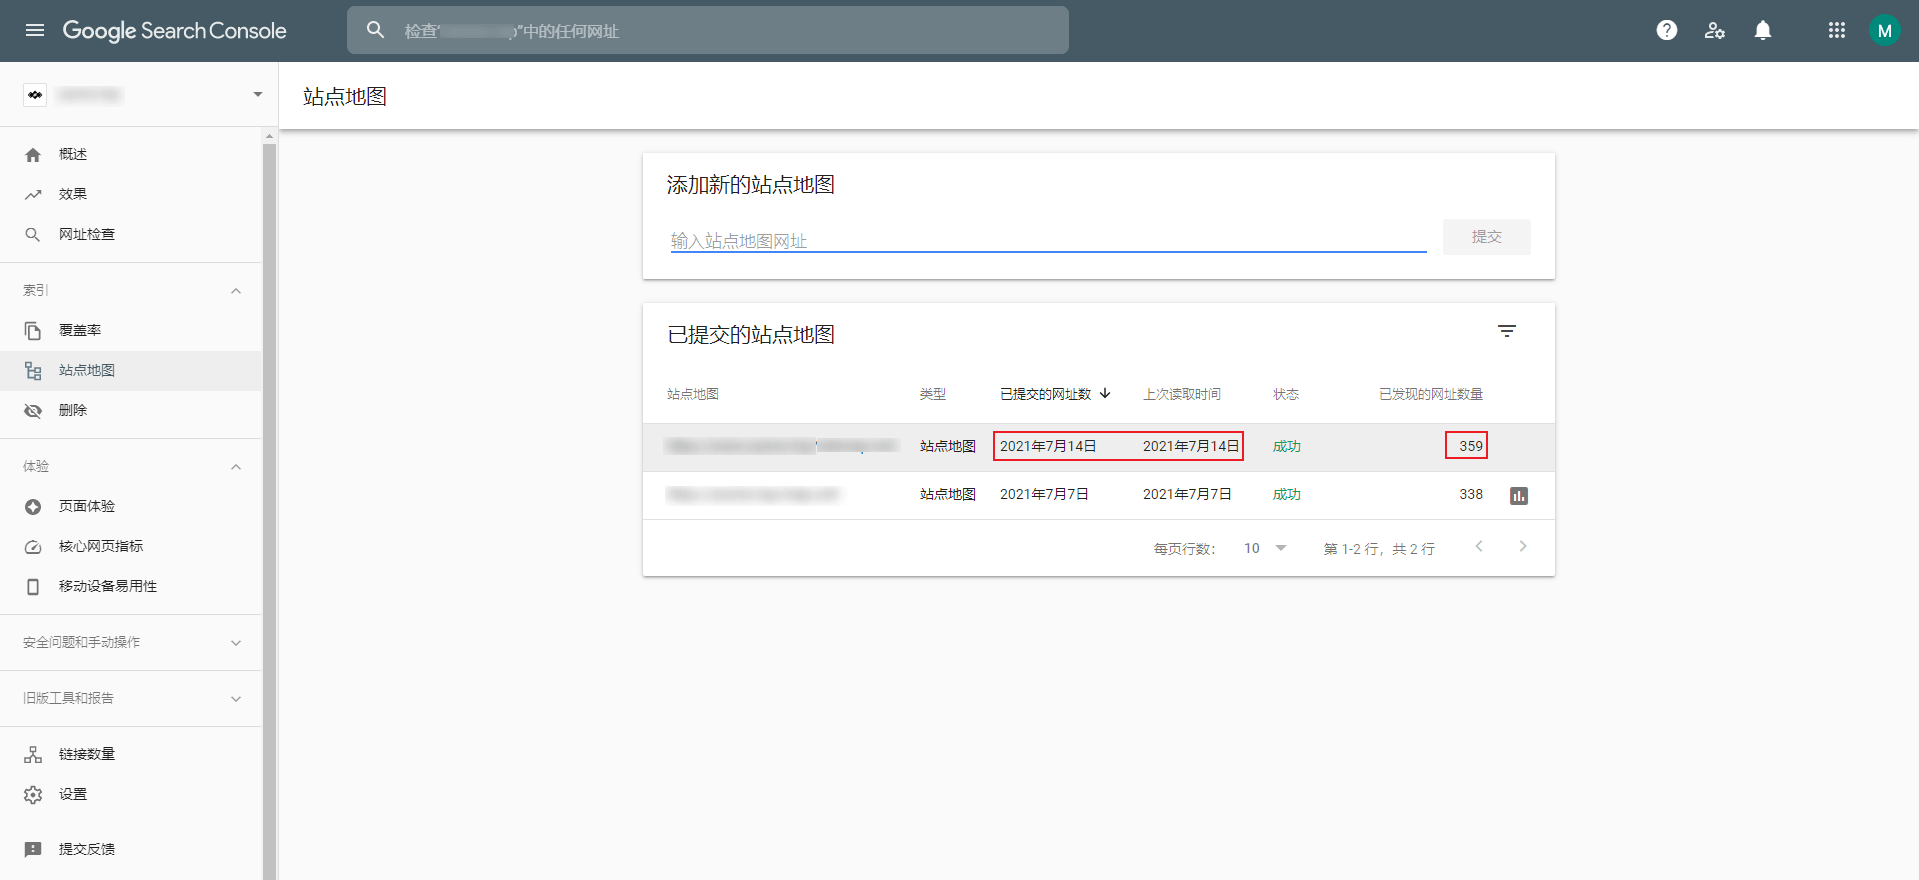
Runtime
评论 0
还没有评论,来说点什么吧。