QA
-
网上已经存在了,为什么重构乌云镜像。
> 因为目前没有整合完美的镜像,要么是只有漏洞库,要么就是只有知识库,两个都有的,漏洞库不完整 -
乌云最后更新在16年,还有必要看吗?
> 漏洞和知识可能会过时,但是思路永远不会过时,可能某一句话就能激发你的灵感。
技术栈
- php(接口)
- MySQL(数据支撑)
- 前端相关(可视化相关)
- python(数据解析,清洗)
资源整合
修复部分
- 修复了tag的格式乱码
- 修复部分链接
图片部分
- 知识库 761MB (798,308,808 字节)
- Bug 26.3GB (28,271,011,283 字节)
- 数据库 673 MB (706,001,756 字节)
后续如果压缩一下图片的话,预估可能会减少1/3的占用存储。
前端构成
当前构成情况
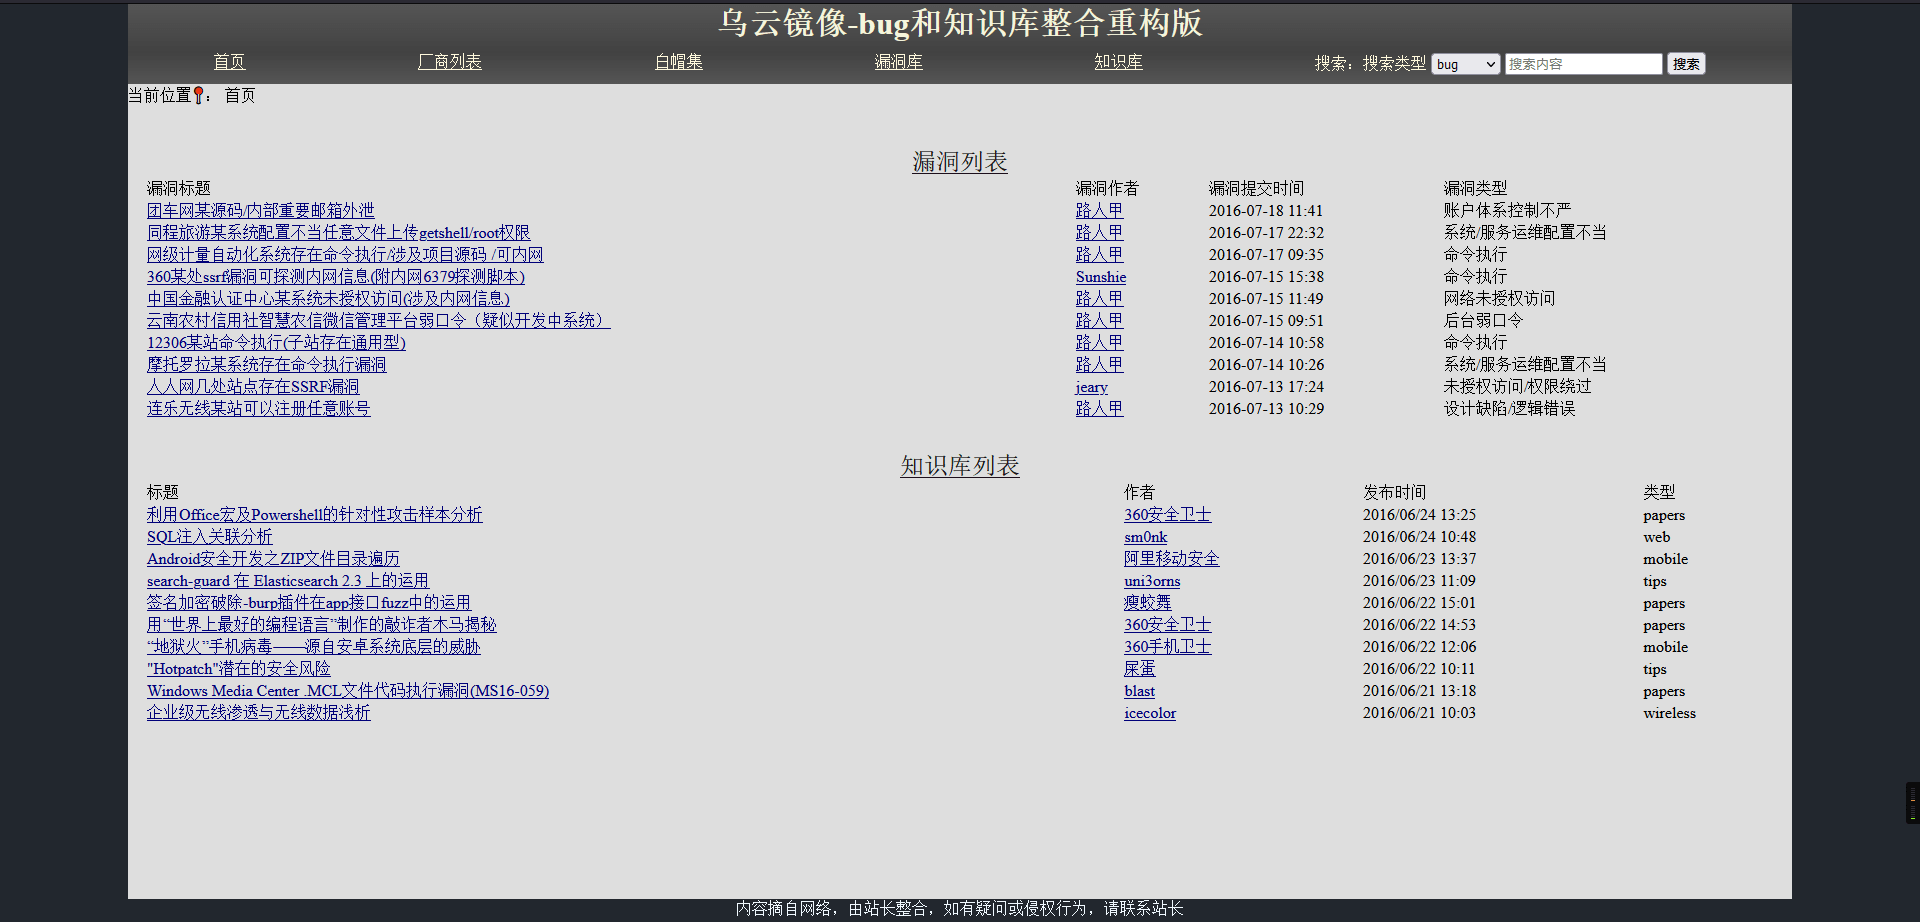
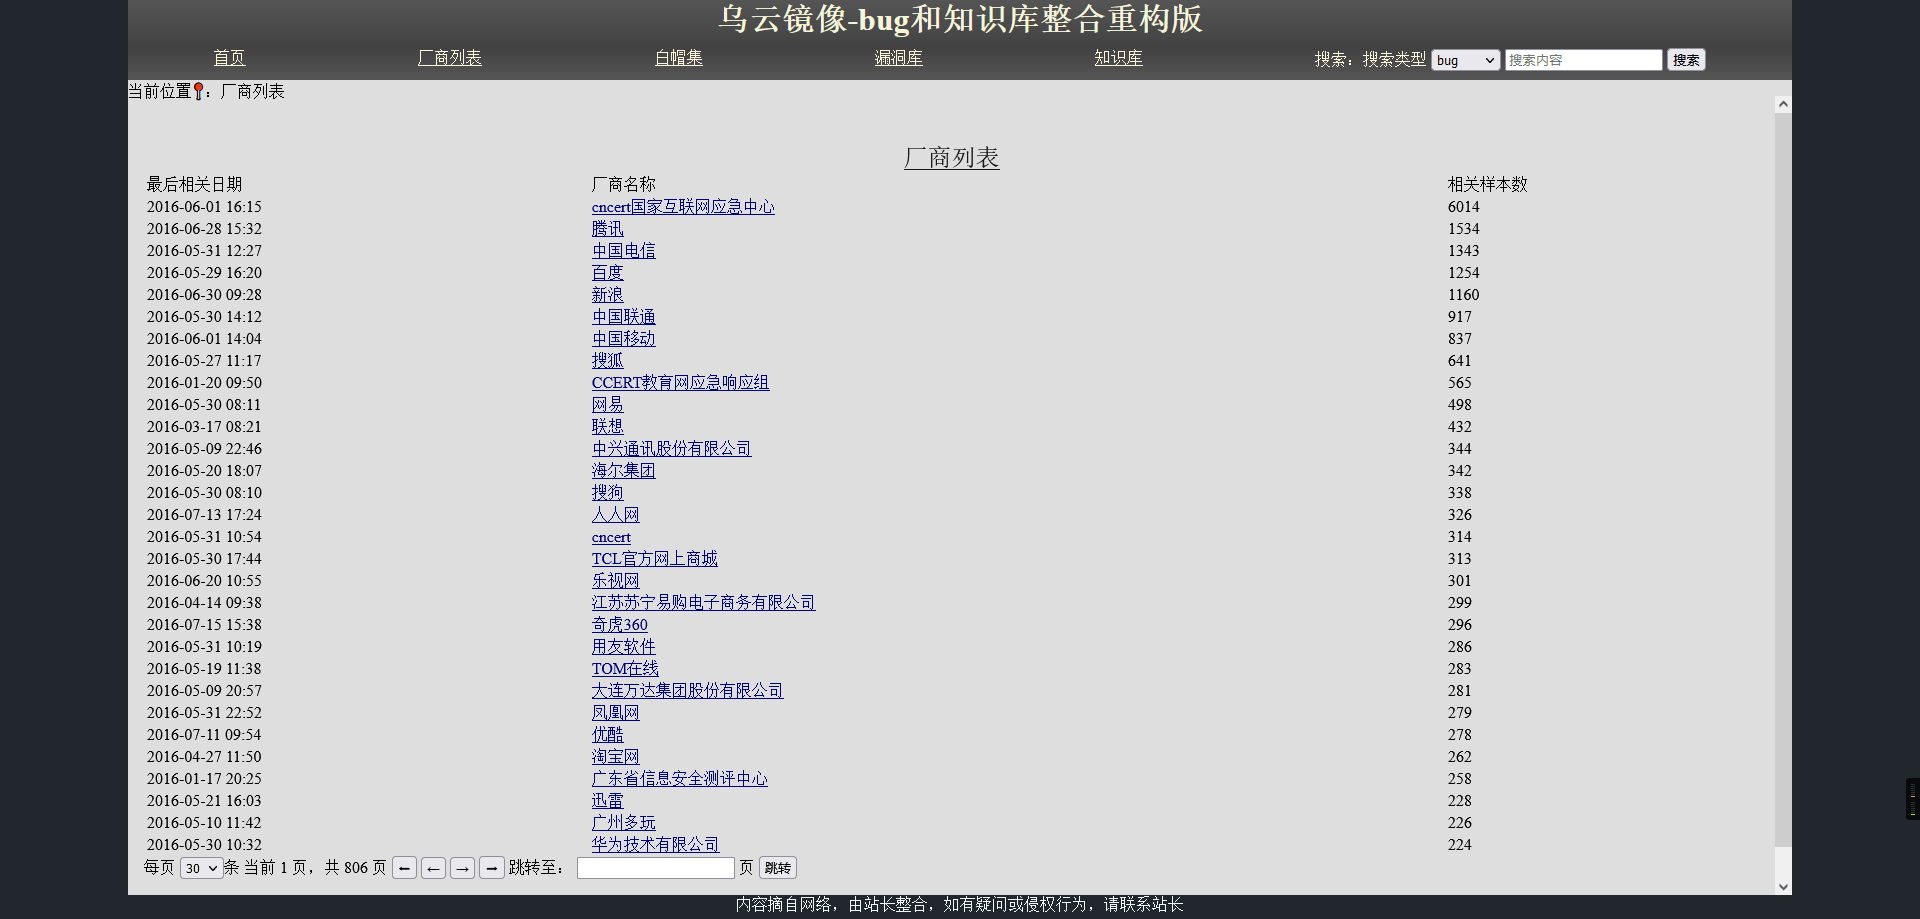
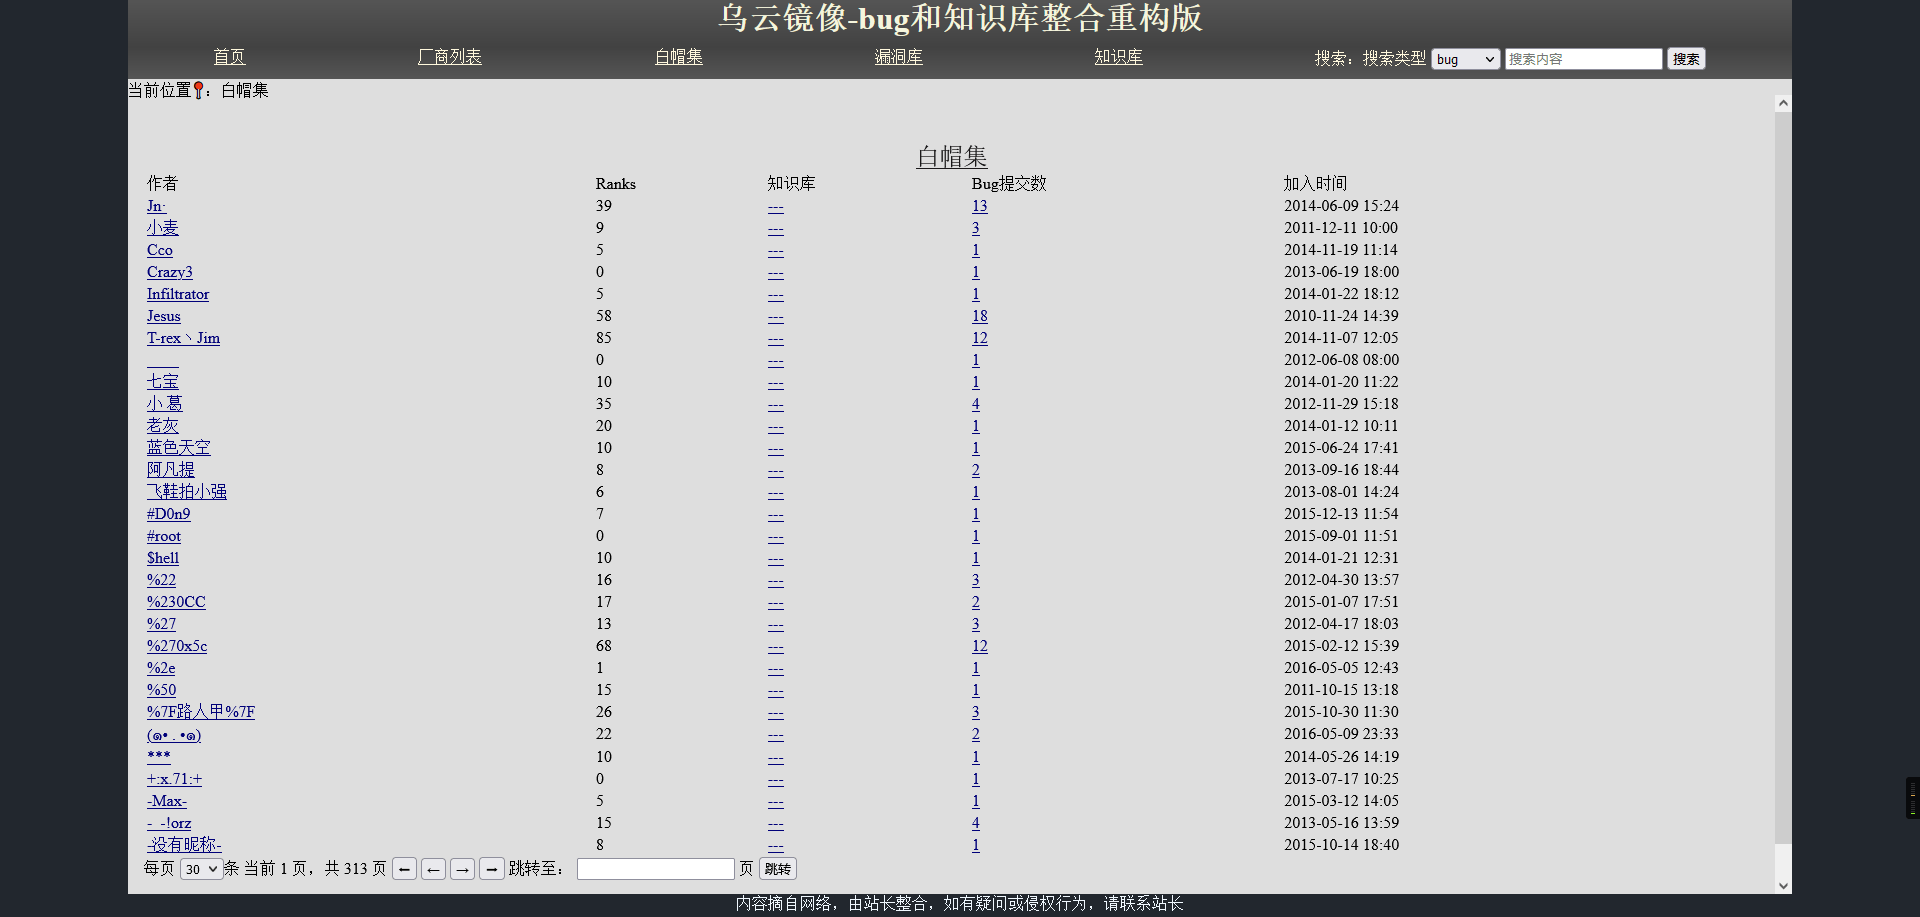
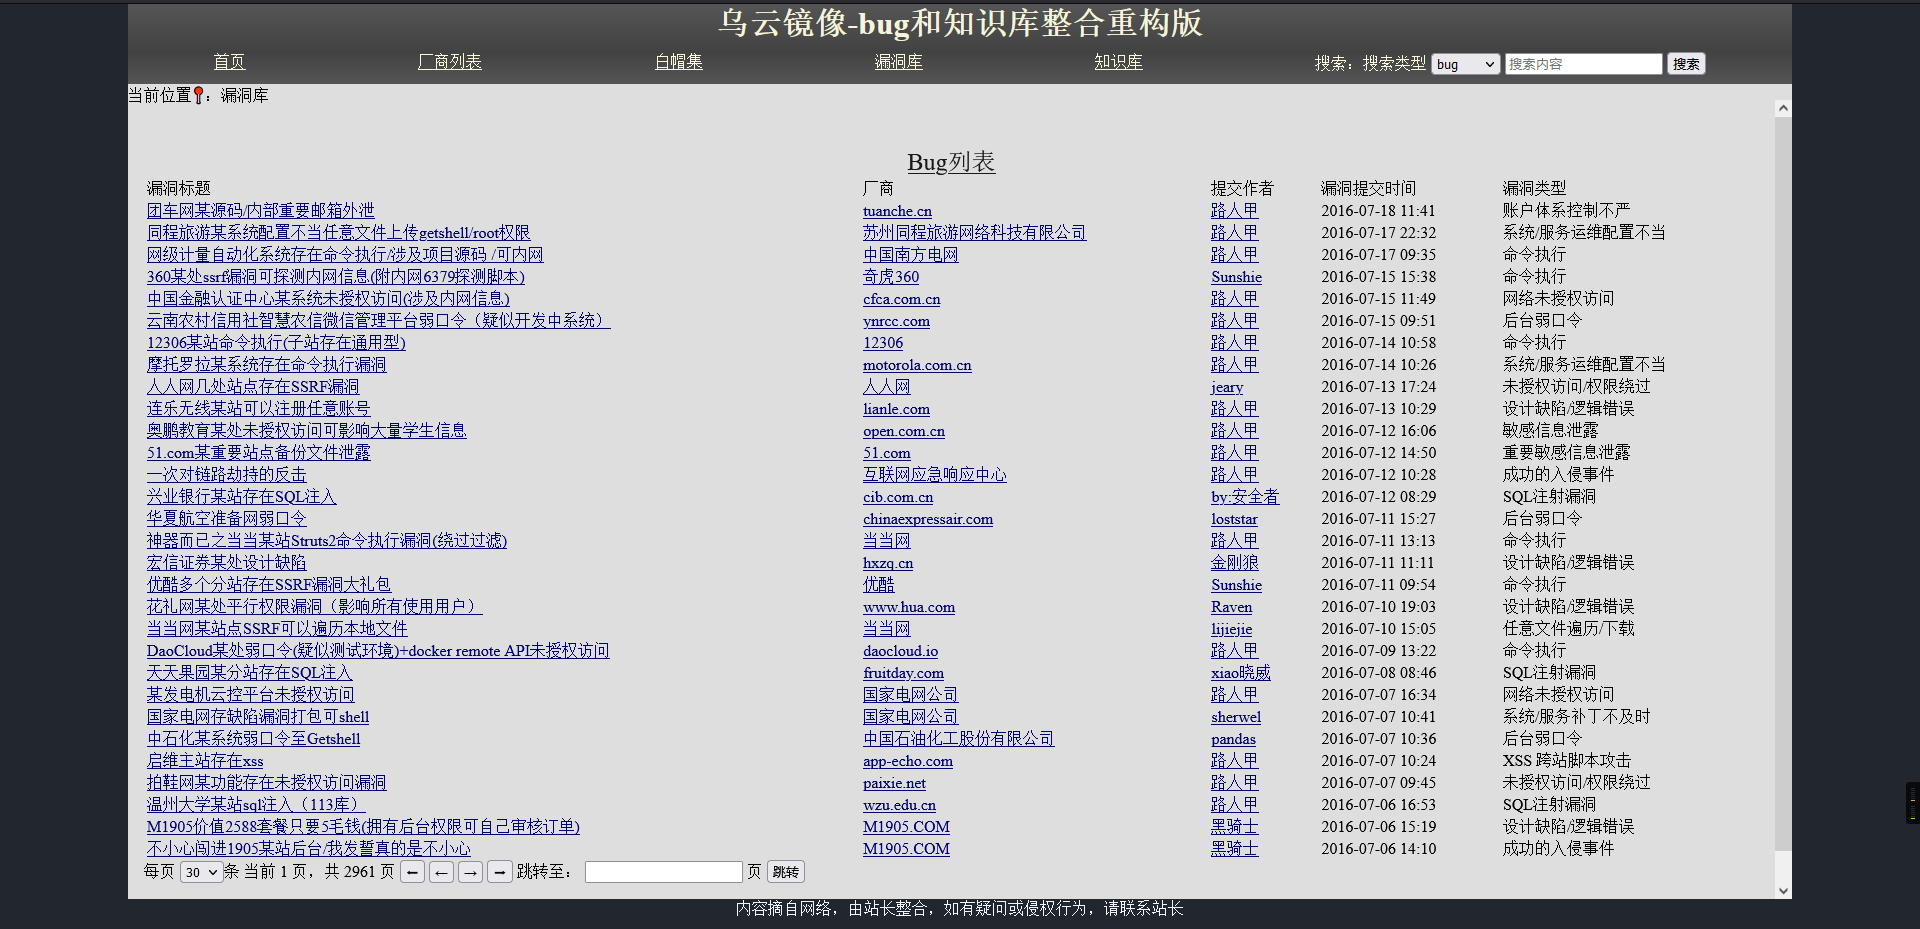
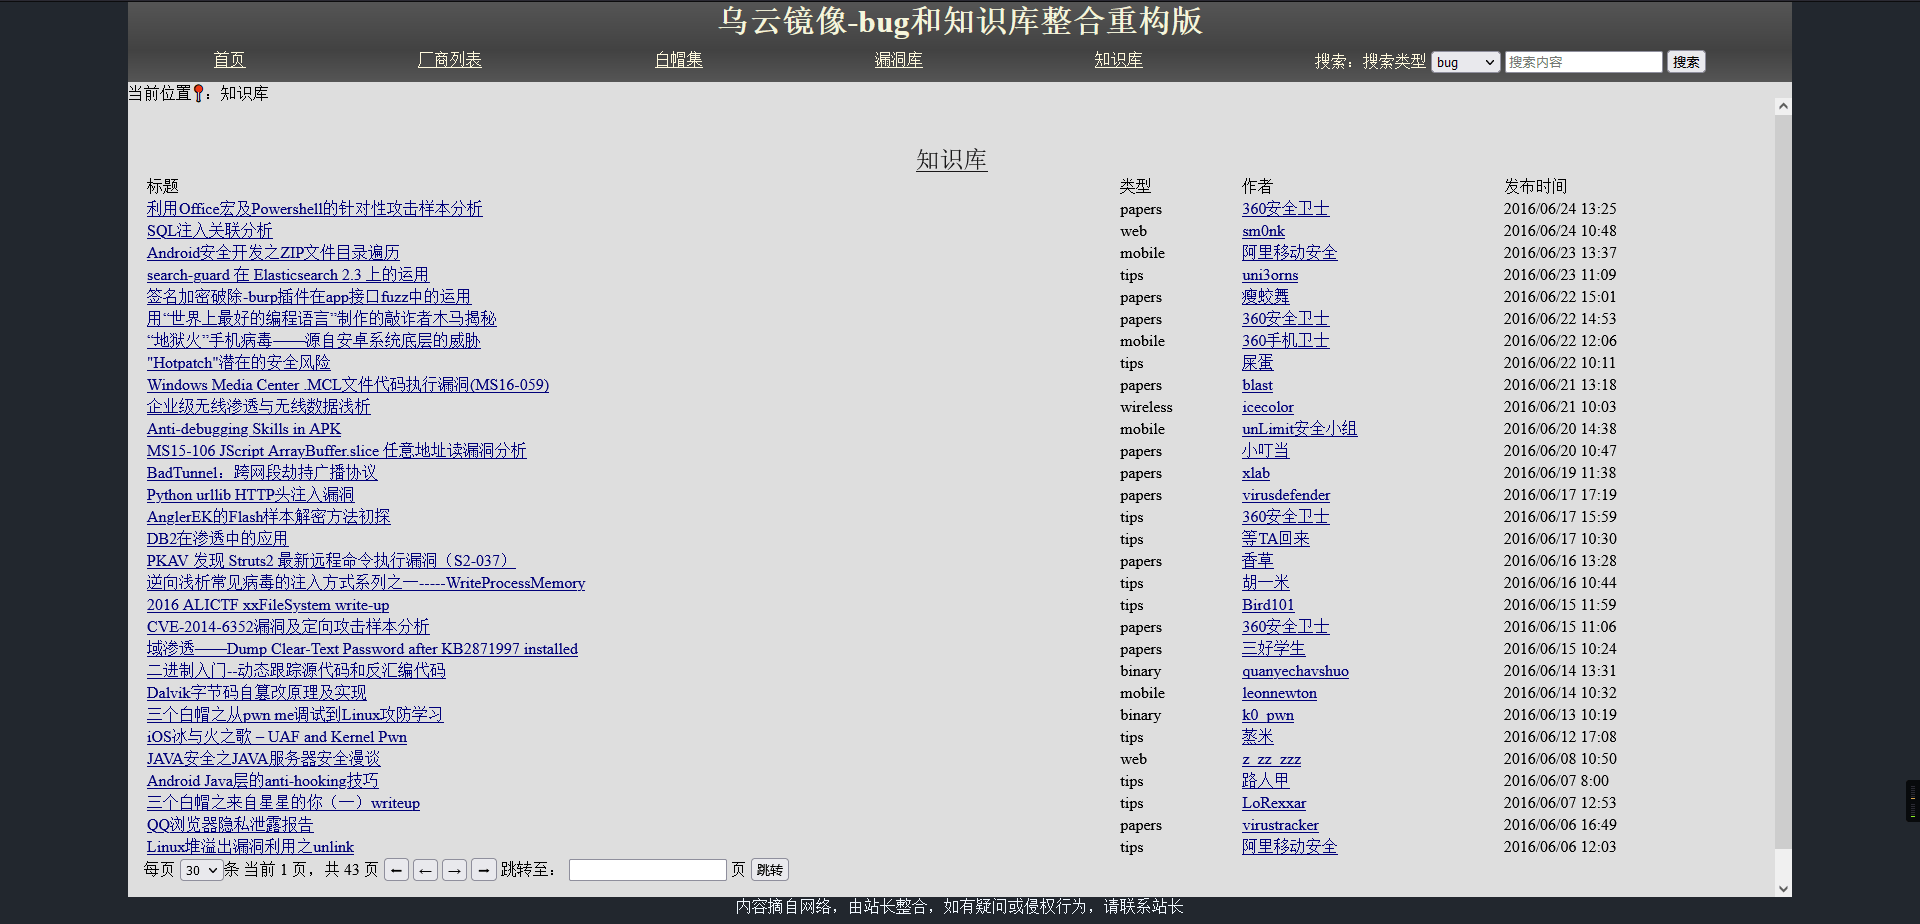
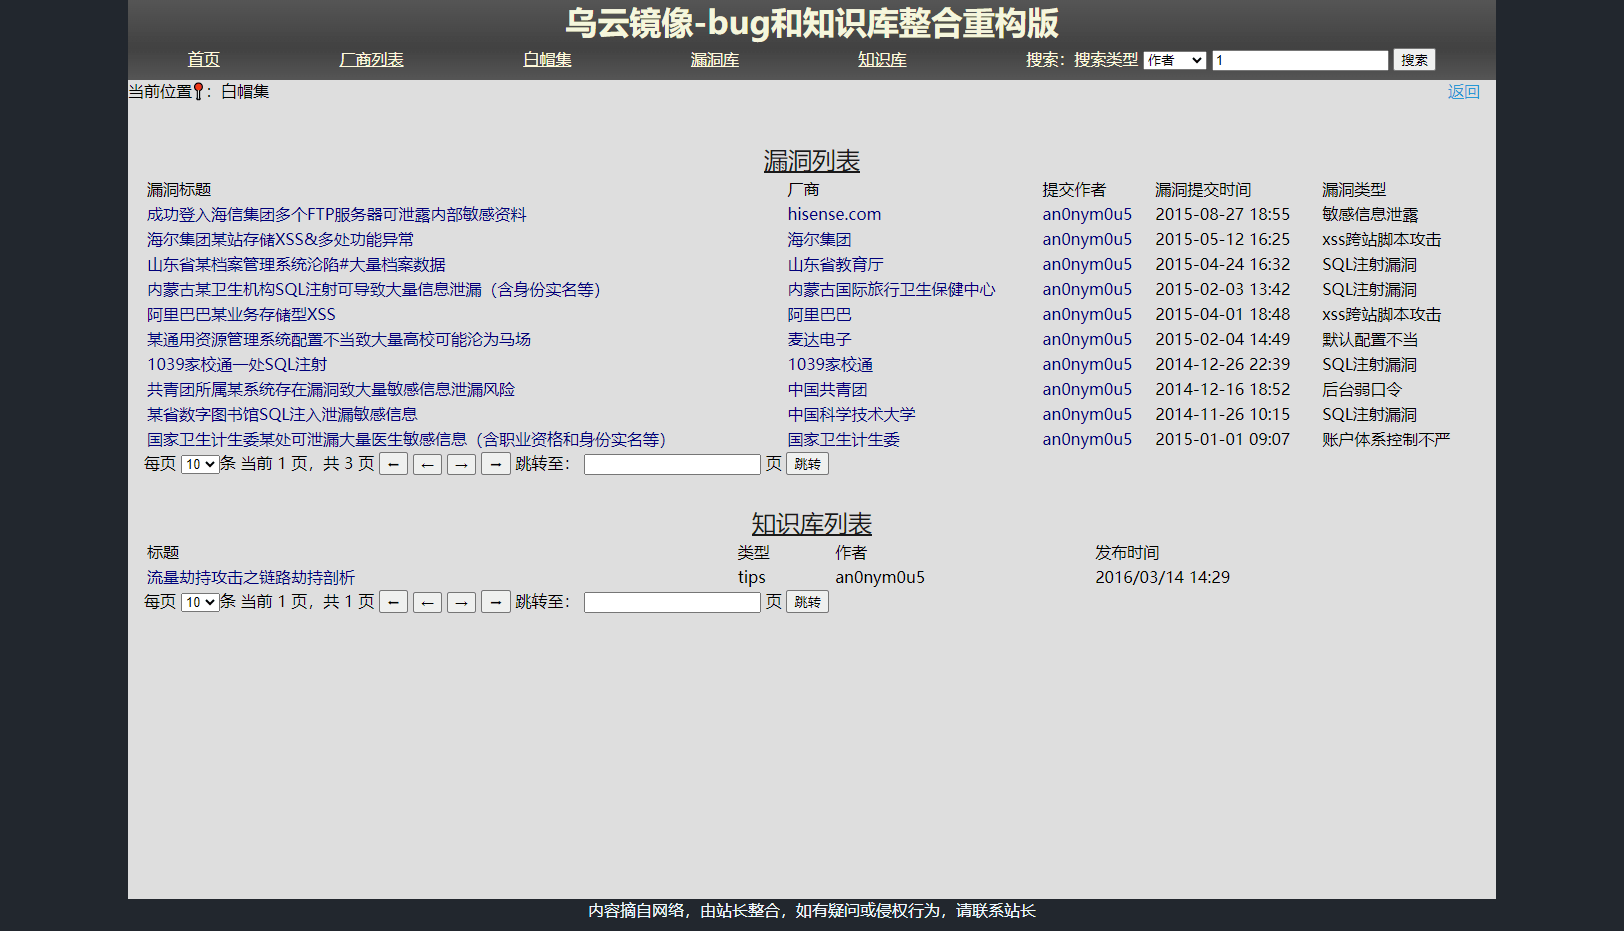
部分清洗过程
import os
import pymysql

base_dir = r'G:\Desktop\wp\wooyun_public\flask\static\drops'
conn = pymysql.Connection(host="localhost", port=****, user='****', password='****', database='wooyun')


def insert_db(wooyun_id, title, types, author, publish_date, comment, context):
    cursor = conn.cursor()
    cursor.execute("""INSERT INTO knowledge(wooyun_id, title,
    types,
    author,
    publish_date,
    `comment_data`,
    context) values (%s,%s,%s,%s,%s,%s,%s)""", (wooyun_id, title, types, author, publish_date, comment, context))
    conn.commit()


def update_count():
    cursor = conn.cursor()
    cursor.execute("""SELECT author,count(1) FROM knowledge group by author""")
    fetchall = cursor.fetchall()
    for i in fetchall:
        author, count = i[0], i[1]
        csor = conn.cursor()
        csor.execute("""SELECT whitehat,count(1) FROM whitehats WHERE whitehat = %s""", (author))
        csor_fetchall = csor.fetchall()
        if csor_fetchall[0][0] is None:
            conn.cursor().execute("""INSERT INTO whitehats(whitehat,know_count) values(%s,%s)""", (author, count))
            print("insert", author, count)
        else:
            conn.cursor().execute("""UPDATE whitehats SET know_count = %s WHERE whitehat = %s""", (count, author))
            print("update", author, count)
        conn.commit()


def get_title(context):
    t = '<title>'
    left = context.find(t)
    right = context.find(' | WooYun知识库</title>')
    return context[left + len(t):right].strip()


def get_author(context):
    t = 'class="author name ng-binding">'
    left = context.find(t)
    right = context.find("</a>", left)
    return context[left + len(t):right].strip()


def get_time(context):
    t = '<time title="'
    left = context.find(t)
    right = context.find('" ui-time="', left)
    return context[left + len(t):right].strip()


def get_comment(context):
    t = '<div id="comment-list">'
    left = context.find(t)
    right = context.rfind('<!-- comment end -->', left)
    right = context[:right].rfind('</div>')
    return context[left:right].strip()


def get_context(context):
    context = context.replace("static/drops/full/", "upload/knowledge/")
    t = """<section class="entry-content ng-binding" ng-bind-html="postContentTrustedHtml">"""
    left = context.find(t)
    right = context.rfind("""</section>""")
    return context[left + len(t):right].strip()


def pre_insert_db():
    listdir = os.listdir(base_dir)
    for file in listdir:
        file_path = os.path.join(base_dir, file)
        if os.path.isdir(file_path): continue
        with open(file_path, 'r', encoding='utf-8') as f:
            file_content = f.read()
            woo_id = file[:-5]
            types = file[:file.find('-')]
            title = get_title(file_content)
            author = get_author(file_content)
            time = get_time(file_content)
            context = get_context(file_content)
            comment = get_comment(file_content)
            insert_db(woo_id, title, types, author, time, comment, context)
            print(woo_id, types, len(title), len(author), len(time), len(comment), len(context))


def clean_tags():
    sql = """select id,wybug_tags from wooyun.bugs """
    cursor = conn.cursor()
    cursor.execute(sql)
    fetchall = cursor.fetchall()
    process = 0
    for i in fetchall:
        process += 1
        ids = i[0]
        old = str(i[1])
        txt = str(i[1])
        find = txt.find("%")
        while find != -1:
            txt = txt[0:find] + txt[find + 3:]
            find = txt.find("%")
        conn.cursor().execute("""UPDATE wooyun.bugs set wybug_tags = %s where id = %s""", (txt, ids))
        conn.commit()
        print(process, len(fetchall))


if __name__ == '__main__':
    # pre_insert_db()
    # update_count()
    clean_tags()
镜像下载
为了方便下载,镜像上传至123pan
因数据量太大了,小小的服务器支撑不住,所以,并未上线体验站。
其实站长也努力了,但是服务器性能实在是不足以支撑,测试期间已经影响了现有的业务运行。
如果需要下载,可以考虑试试这个。
ℹ:数据库导入需要先创建一个wooyun的库,然后写入到wooyun库里面。
ℹ:db_wooyun.zip 乌云数据库文件
ℹ:api_old_wooyun.rar 原始的php页面
ℹ:wooyun.zip 自己做的php页面
下载链接:
https://www.123pan.com/s/rSNuVv-86FmH.html
提取码:WZJM
评论 0
还没有评论,来说点什么吧。