引言
如果要动生产环境,并且做的时陌生的领域,一定要在本机上先搭建测试,然后在开发环境(尽可能的和生产环境保持一致)进行测试,无误后再动生产,做到双保险。
错误信息
mysql> show slave status\G
*************************** 1. row ***************************
               Slave_IO_State: Waiting for master to send event
                  Master_Host: ***.***.***.***
                  Master_User: slave
                  Master_Port: ****
                Connect_Retry: 60
              Master_Log_File: mysql-bin.000056
          Read_Master_Log_Pos: 156905389
               Relay_Log_File: relay-log.000002
                Relay_Log_Pos: 756
        Relay_Master_Log_File: mysql-bin.000056
             Slave_IO_Running: Yes
            Slave_SQL_Running: No
              Replicate_Do_DB:
          Replicate_Ignore_DB:
           Replicate_Do_Table:
       Replicate_Ignore_Table:
      Replicate_Wild_Do_Table:
  Replicate_Wild_Ignore_Table:
                   Last_Errno: 1032
                   Last_Error: Coordinator stopped because there were error(s) in the worker(s). The most recent failure being: Workeperformance_schema.replication_applier_status_by_worker table for more details about this failure or others, if any.
                 Skip_Counter: 0
          Exec_Master_Log_Pos: 156849000
              Relay_Log_Space: 57713
              Until_Condition: None
               Until_Log_File:
                Until_Log_Pos: 0
           Master_SSL_Allowed: No
           Master_SSL_CA_File:
           Master_SSL_CA_Path:
              Master_SSL_Cert:
            Master_SSL_Cipher:
               Master_SSL_Key:
        Seconds_Behind_Master: NULL
Master_SSL_Verify_Server_Cert: No
                Last_IO_Errno: 0
                Last_IO_Error:
               Last_SQL_Errno: 1032
               Last_SQL_Error: Coordinator stopped because there were error(s) in the worker(s). The most recent failure being: Workeperformance_schema.replication_applier_status_by_worker table for more details about this failure or others, if any.
  Replicate_Ignore_Server_Ids:
             Master_Server_Id: 1739
                  Master_UUID: 988480aa-728b-11eb-b830-00155d07057e
             Master_Info_File: mysql.slave_master_info
                    SQL_Delay: 0
          SQL_Remaining_Delay: NULL
      Slave_SQL_Running_State:
           Master_Retry_Count: 86400
                  Master_Bind:
      Last_IO_Error_Timestamp:
     Last_SQL_Error_Timestamp: 210901 09:33:52
               Master_SSL_Crl:
           Master_SSL_Crlpath:
           Retrieved_Gtid_Set:
            Executed_Gtid_Set:
                Auto_Position: 0
         Replicate_Rewrite_DB:
                 Channel_Name:
           Master_TLS_Version:
1 row in set (0.01 sec)
项目背景
- Hadoop大数据平台
- MySQL5.7.11
- 等等
TODO
因为MySQL负载有点大了,所以为了分担查询负载,故主从复制,让从来分担主的负载。
执行流程
备份数据库
mysqldump -uroot -pxxxxxxxx --databases -R xxx xxx xxx xxx > db.sql
查看log和pos,并且记录数据
show master status;
复制到目标服务器
scp db.sql
root@xxx.xxx.xxx.xxx:/tmp/
恢复数据
mysql -uroot -pxxxxxx <db.sql
设置Slave以及开启
change master to master_host='xxx.xxx.xxx.xxx', master_user='slave',
master_password='xxxxxx', master_port=xxxx,
master_log_file='mysql-bin.000056', master_log_pos=156919230,
master_connect_retry=60;
Start slave;
:x: 报错
错误分析和解决
执行SQL语句:
select * from performance_schema.replication_applier_status_by_worker\G
*************************** 1. row ***************************
         CHANNEL_NAME:
            WORKER_ID: 1
            THREAD_ID: NULL
        SERVICE_STATE: OFF
LAST_SEEN_TRANSACTION: ANONYMOUS
    LAST_ERROR_NUMBER: 1032
   LAST_ERROR_MESSAGE: Worker 0 failed executing transaction 'ANONYMOUS' at master log mysql-bin.000056, end_log_pos 156848969; Could not execute Update_rows event on table cmf.cm_version; Can't find record in 'cm_version', Error_code: 1032; handler error HA_ERR_END_OF_FILE; the event's master log FIRST, end_log_pos 156848969
 LAST_ERROR_TIMESTAMP: 2021-09-01 09:21:00
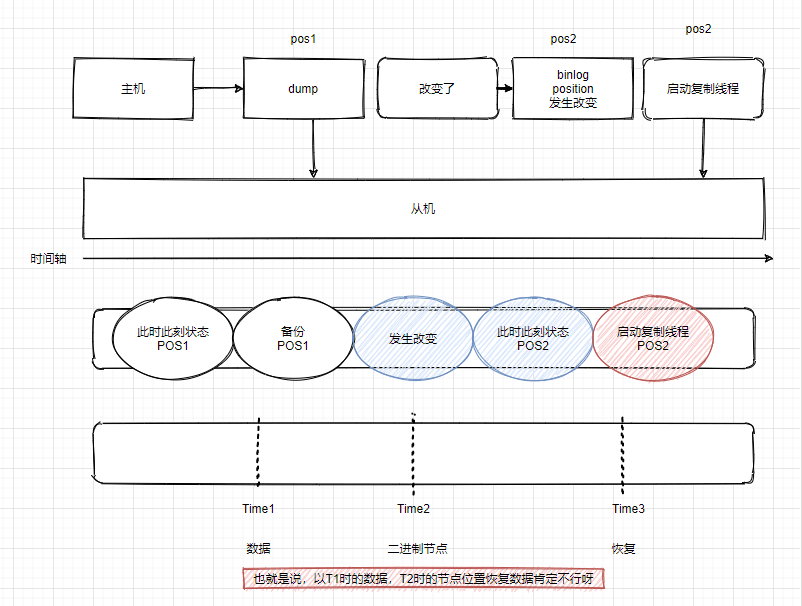
查看主表的cm_version,发现与从表对应不上,过一会儿刷新还会变,emm,这可咋整,回家睡觉了,结果今天来到公司,猛然间就想到了这一点,这样的话也可以通过show master status\G来验证,因为每过一会儿pos都会变,那么问题就大概解决了。也就是说当dump和查看pos时,需要复制SSH渠道,同时进行,因为cmf.cm_version中数据总是在变化,而改变时binlog会改变,因此pos也变了,所以需要同时进行,保证pos与dump一致。
来张图解释一下
评论 0
还没有评论,来说点什么吧。